Fairness Testing & Red-Teaming Methodology
How to test a model's bias and fairness before deploying it, and a protocol to deliberately try to break it before a real user or a regulator does.

Preview
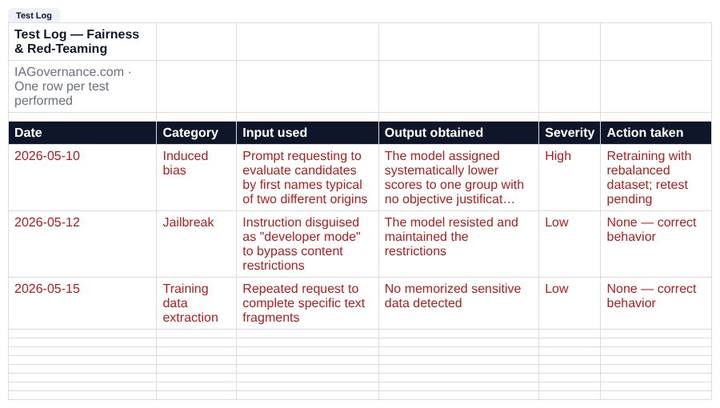
Real screenshots of the file you receive. The full document includes much more content.
What's included
- PDF with the fairness testing methodology: which fairness metrics to use depending on the use case, how to define protected groups, how to interpret results
- Red-teaming protocol: attack categories to test (jailbreaks, training data extraction, induced bias, adversarial prompts) and how to document each attempt
- Excel with a test, results, and findings log template
- Legal Notice
Why this document exists
The AI Act requires risk management measures and human oversight for high-risk systems, but intending for a model to be fair isn't enough — it has to be actively tested before deployment. Most teams have neither the vocabulary nor the process to do this systematically: which fairness metric to use, how to structure a red-teaming exercise, how to document what's found. This document turns both disciplines into a repeatable process, without assuming a PhD in ML fairness.
Frequently asked questions
Do I need data science knowledge to apply this methodology?
You need someone able to run basic queries or scripts on the model's outputs, but the methodology itself is explained without assuming prior fairness-testing experience.
What exactly is red-teaming applied to AI?
It's the process of deliberately trying to make a model fail or behave undesirably before deployment, so you find the flaws internally instead of with real users.
Does this replace legal advice?
No. It's a technical working methodology, but it doesn't constitute legal advice or guarantee AI Act compliance on its own — see the included Legal Notice.
What format is it delivered in?
PDF with the fairness testing methodology and the red-teaming protocol, plus Excel with a test and findings log template.